Labeling
Run your labeling team inside the flow — work is handed out for you, and every image’s state is visible on the canvas.
In OvalBee, labeling is part of the flow, not a separate project you export data to and import back from. People work in stages, and each stage is a node. The dataset an image sits in tells you where it is in the process. Start with one labeler and one reviewer, and grow from there: send hard cases to an expert, check work automatically before review, or send rejected images back for another try.
How images move
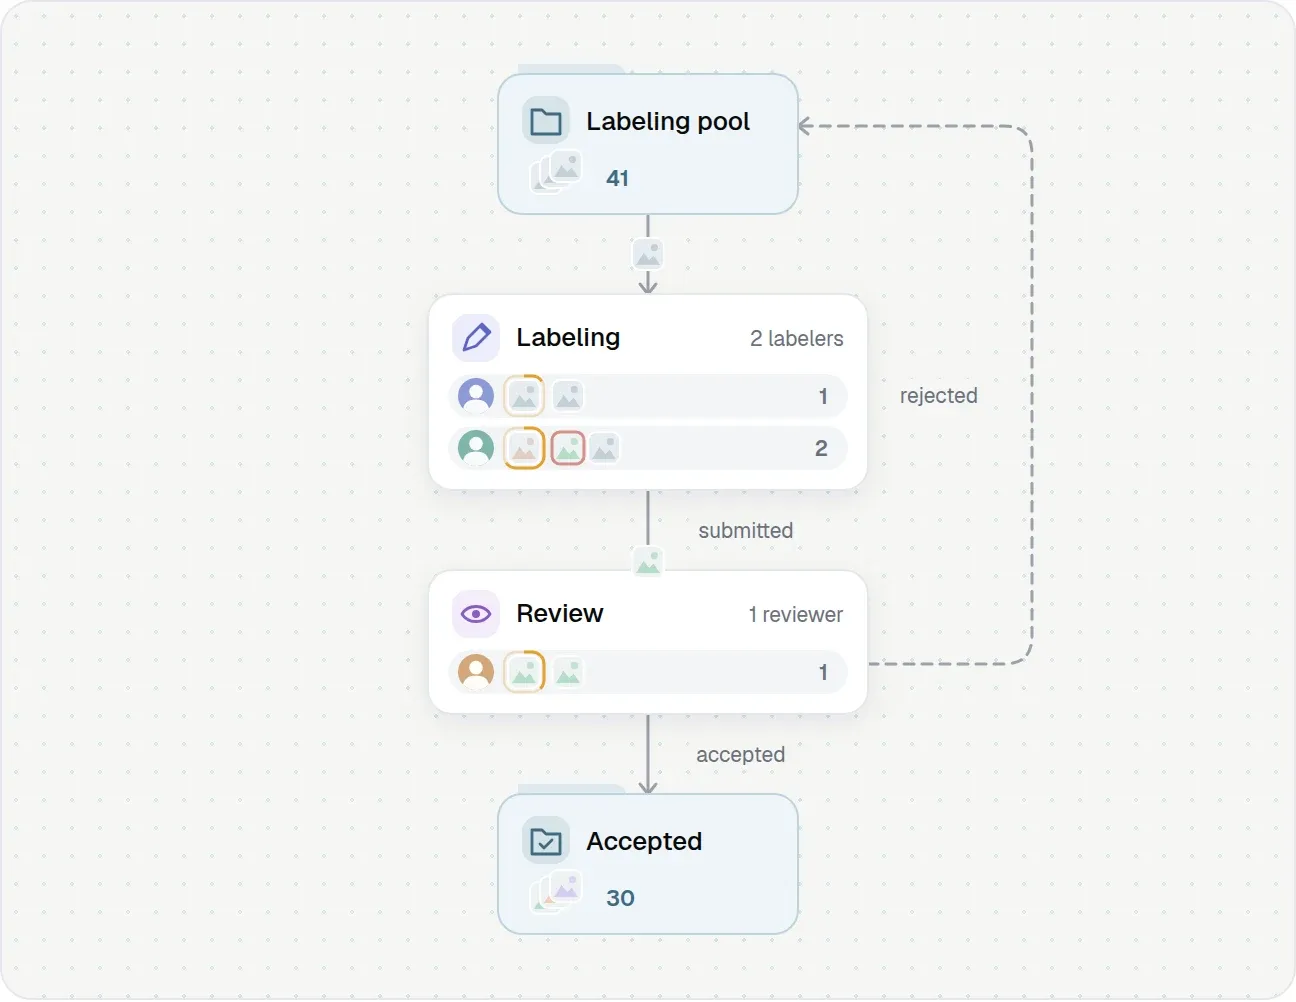
- Labeling pool. Images wait here until a labeler takes them.
- Labeling. Each labeler gets their own queue of images and annotates them.
- Review. A reviewer checks each image and accepts or rejects it.
- Rework. Rejected images go back to the pool, and a labeler fixes them.
- Results. Accepted images land in the final dataset.
People work in stages: Labeling and Review nodes. Everything between them is a dataset. An image is always in exactly one dataset, so you can open any stage and see what is waiting, skipped, rejected or accepted right now.
Decision buttons
Labeling and Review share one simple idea. Each has a Decision buttons setting: a list of pairs, each a button name and a dataset. Every pair becomes a button in the annotation tool. Press it, and the image moves to that dataset with its annotations, right away.
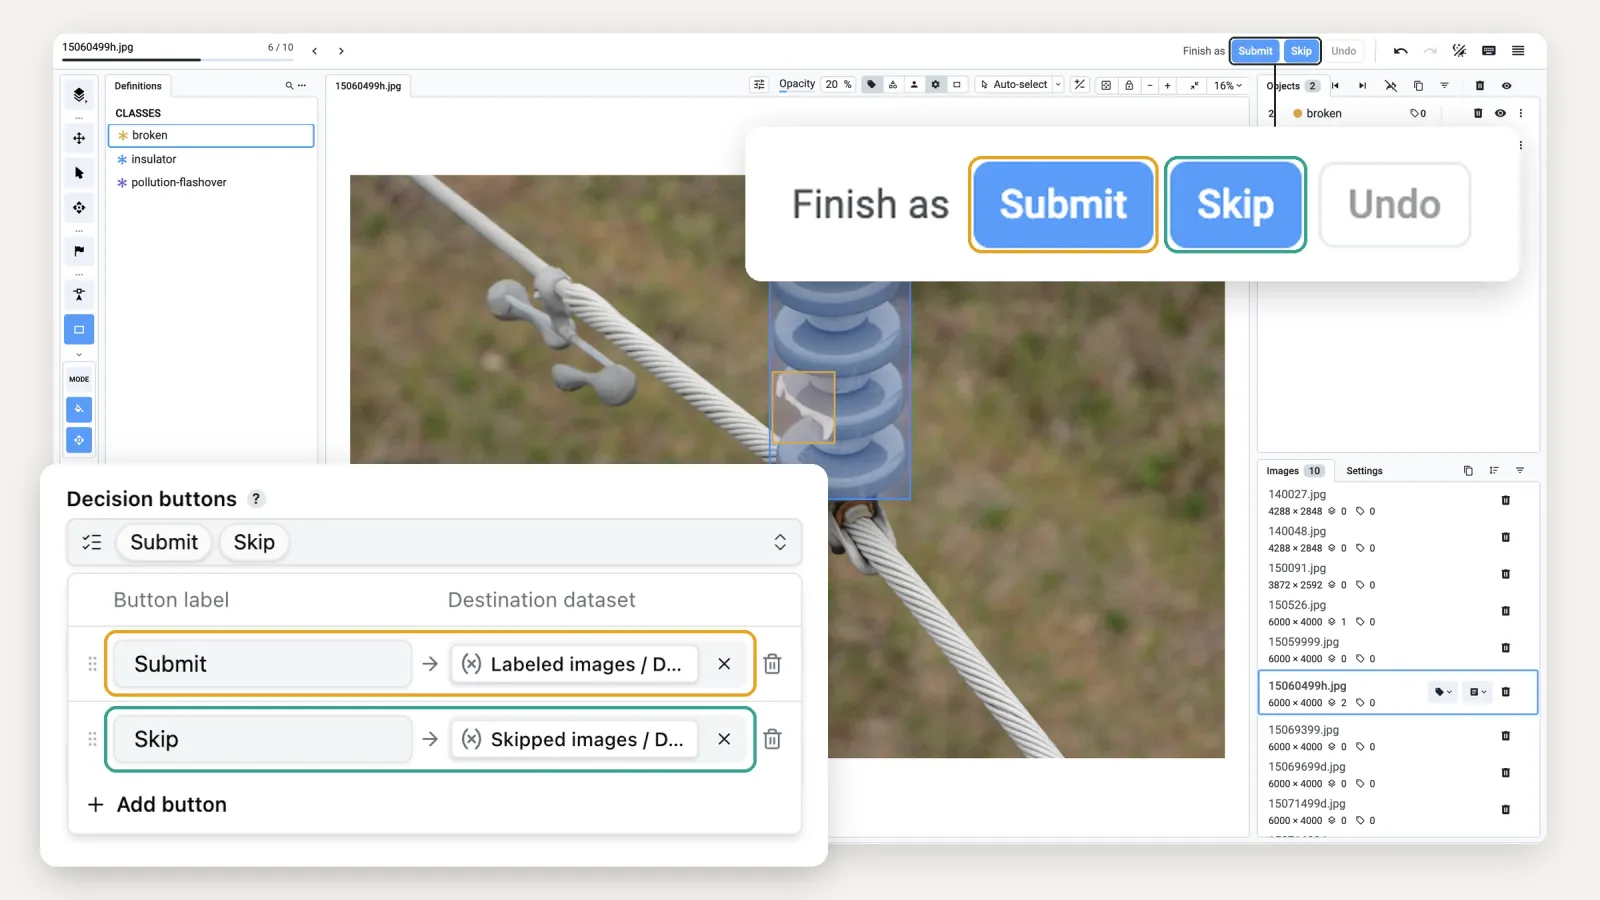
A new Labeling node has Submit and Skip. A new Review node has Accept and Reject. You choose the buttons and where they lead, so you design the process:
- Add a Needs expert button that feeds a second Labeling stage for your specialist.
- Put a Labeling gate between labeling and review, so rule-based checks send broken annotations straight back.
- Send accepted images straight into a training dataset.
Rejected images wait in their dataset until a Return to labeling node moves them back to the pool. Run it by hand, or put it on a schedule so rework starts on its own.
How work is handed out
When a Labeling or Review node runs, it gives each assigned person a private queue from the source pool, up to the stage’s Batch size. The rest stays in the pool for others. Several people work at the same time and never get the same image.
- Pressing a button moves the image on and refills the queue right away.
- New images in the source pool go straight to queues with free space, so finished labeling reaches review without waiting.
- Work that sits in a queue too long goes back to the pool, so a forgotten batch never blocks the project. You set the time on the node.
- Removing a person from a stage sends their queue back to the pool.
- A stage hands out the oldest images first. Set its Queue order to Highest anomaly score first and it starts with the most unusual images instead, using the scores Embedding anomalies saves when Save scores to images is on.
- Each stage also runs every 15 minutes on its own to keep queues in order.
An image is always in exactly one place, and the pool holds only work nobody has taken. That’s why the counts on the canvas are always right.
Kinds of stages
- Labeling — people draw and fix annotations.
- Review — people check annotations without changing them. A fix goes back through a labeling stage.
- Label train, validation and test — labels three splits from one queue and keeps them apart, so a model is never scored on images it trained on.
Classes
Each stage has a Classes input: the ontology people label with. Tick some classes to show only those. The datasets after the stage use the same ontology, so labels stay consistent all the way through the flow.
When the list of classes is still growing, turn on Labelers can add classes and tags. New classes are saved in the ontology as a new version, and every later stage sees them.
The annotation tool
People open the annotation tool in a new browser tab: with Open annotation tool on the node, or from the Labeling page in the main sidebar. The tool shows their current batch, the classes, the drawing tools and the stage’s decision buttons.
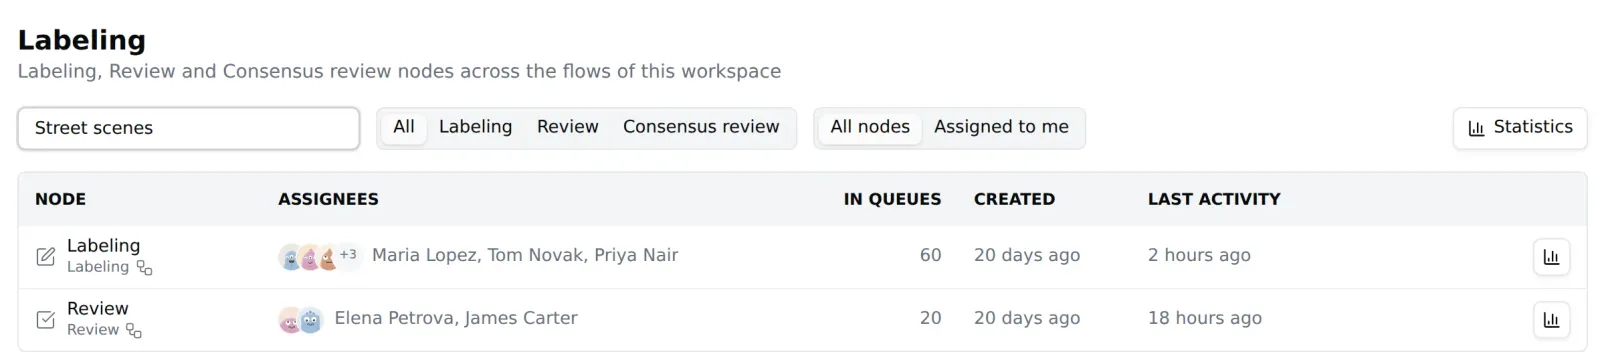
The Labeling page lists every labeling stage in the workspace, with the people assigned, the images in their queues and the last activity. Switch to Assigned to me to see only your own tasks. On Home, the My labeling tasks block shows the same for you.
- AI-assisted segmentation is available in the tool while an interactive segmentation model is deployed in the workspace.
- A stage creates its queues on its first run. Until then, Open annotation tool asks you to run the node.
Tracking progress
Labeling and Review nodes show a live chart of their stage on the canvas, in total and per person. Labeling shows what is in progress and what is labeled. Review shows what is in progress, accepted and rejected. The chart updates about a second after each button press.
For the full picture, open Labeling statistics: pace and backlog per stage, time in the tool, objects per class, review results for each labeler and the history of every image.
Labeling in Supervisely
If your team already labels in Supervisely, keep it there. The Labeling queue manager and Labeling jobs manager nodes run Supervisely queues or jobs from a flow. They copy each stage — waiting, labeling, on review, rework, accepted — into OvalBee datasets, so the rest of the flow builds on the result.
Start from a template
The template library has ready labeling flows:
- Basic labeling pipeline — labeling and review in a loop until every image is accepted.
- Labeling with expert — hard cases go to a specialist.
- Labeling with auto quality check — rules check every submission before a reviewer sees it.
- Active learning with live training — label in small batches while a model learns and picks the next images.
- Supervisely queue labeling and Labeling jobs in Supervisely — the same in Supervisely.
See Organize labeling for how to pick one and make it yours.
Related pages
- Labeling statistics — numbers for every stage, person and image.
- Organize labeling — the same ideas as a step-by-step use case.
- Datasets and versions — pools and outcomes are datasets.
- Ontologies — the classes people label with.